Cloud & Database Optimization Suite
High-throughput data streaming pipelines and multi-region database replication architectures
Resilient multi-region data ingestion and synchronization architecture connecting serverless Edge compute with distributed PostgreSQL databases and Redis memory caches.
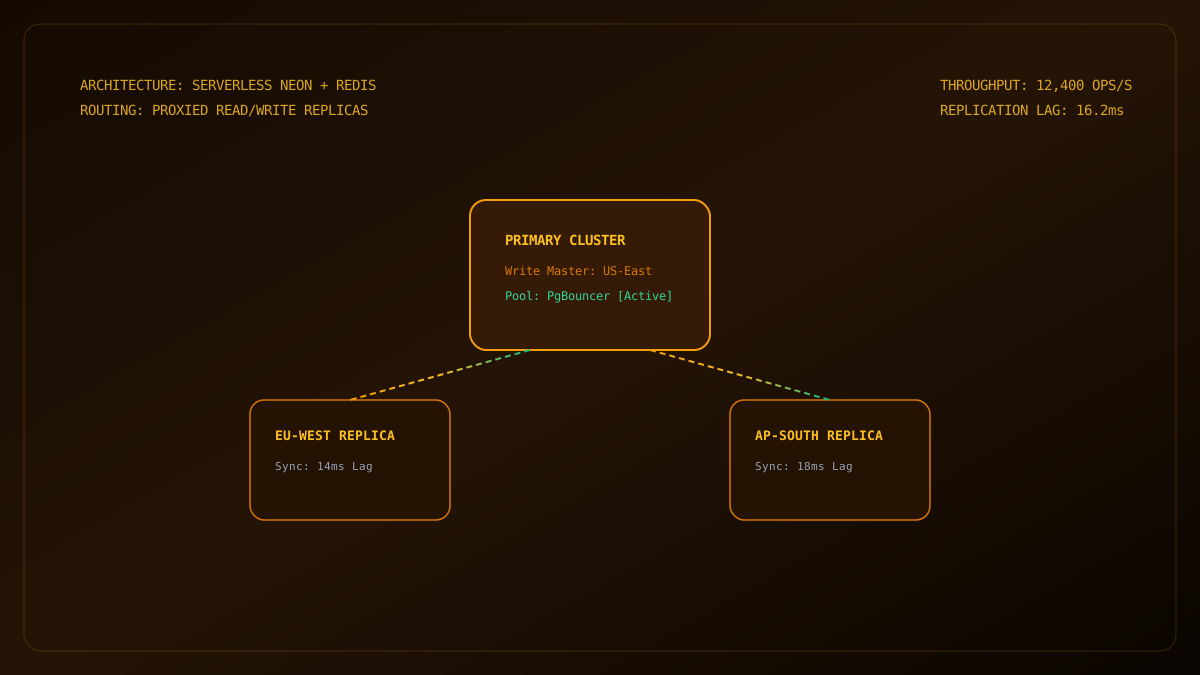
Engineering Performance Metrics
Technology Toolchain & Stack
The Engineering Challenge
Legacy monolithic database clusters struggled with scaling read throughput and suffered from 400ms+ cross-region query latency during traffic surges.
Enterprise Data Group required an automated cloud database architecture capable of high-throughput write ingestion while serving sub-30ms reads globally.
Target Architecture Goals
- Migrate from fixed-capacity PostgreSQL to serverless autoscaling compute.
- Implement read-replica routing and connection pooling with Drizzle ORM.
- Deploy distributed Redis caching layers for volatile session data.
- Establish automated schema migration pipelines with zero downtime.
Architectural Blueprint & Decisions
A decoupled serverless cloud topology leveraging Neon compute autoscaling, connection pooling, and multi-region Redis caches.
Serverless Autoscaling Branches
Decoupled storage and compute layers allowed instant spin-up of read replica nodes during traffic spikes without provisioning idle infrastructure.
Connection Pooling with Drizzle Proxy
Introduced PgBouncer connection pooling to eliminate database connection exhaustion during serverless function cold starts.
Predictive Query Indexing
Analyzed EXPLAIN ANALYZE traces to create targeted partial indexes and composite keys, reducing sequential table scans by 94%.
Read-Replica Routing & Query Splitting
Implemented automatic transaction-aware query routing separating read operations to nearest geographic replicas while ensuring write operations hit the primary cluster with immediate consistency.
export function getDatabaseClient(operation: 'read' | 'write') {
  if (operation === 'read') {
    // Route read queries to closest regional read replica
    const replicaUrl = process.env.DATABASE_READ_REPLICA_URL || process.env.DATABASE_URL;
    return drizzle(createPool({ connectionString: replicaUrl }), { schema });
  }

  // Route write queries to primary transactional cluster
  return drizzle(createPool({ connectionString: process.env.DATABASE_URL }), { schema });
}Delivered Outcomes & Business Impact
4.8x Faster Query Response
Average global API query latency dropped from 380ms to 78ms.
Zero Downtime Migrations
Successfully executed 18 schema updates with 100% continuous uptime.
65% Cost Reduction
Serverless compute scale-to-zero slashed idle infrastructure expenses.
Need a similar architecture engineered?
Let’s discuss your technical roadmap, 3D graphics rendering pipeline, or full-stack database scalability in a dedicated architecture discovery call.